

Region-Based Set Reconciliation
When two peers wish to synchronise willow data, they typically start by determining which Areas they share an interest in. Once that is done, they need to bring each other up to speed so that both peers have the most recent data in the intersection of their interests. This document presents a strategy for efficiently accomplishing that task.
Given the AuthorisedEntries that the peers have available, there can be two cases that necessitate data exchange. First, one peer might have an AuthorisedEntry that the other does not have, and second, the peers might hold nonequal parts of the Payload of some common AuthorisedEntry.
As a first step to solving the problem, we simplify it. If AuthorisedEntries contained information about locally available Payload bytes, then both cases would merge into a single case: one peer might have a datum that the other lacks. Hence, we do not synchronise AuthorisedEntries directly, but LengthyAuthorisedEntries:
An AuthorisedEntry together with information about how much of its Payload a peer holds. The AuthorisedEntry in question.}The task of the two peers then becomes conceptually simple: they each have a set of LengthyAuthorisedEntries, and they need to inform each other about all LengthyAuthorisedEntries the other party does not have, that is, they each need to compute the union of their two sets. In the scientific literature, this problem is known as set reconciliation (Minsky et al., 2003).
Once the two peers have reconciled their sets, they can filter out AuthorisedEntries that overwrite each other, and they can separately request any missing (suffixes of) Payloads. Going forward, we thus concentrate on the set reconciliation part only.
To perform set reconciliation, we adapt the approach of range-based set reconciliation (Meyer, 2023).
Range-based set reconciliation solves the problem recursively. To reconcile two sets, one peer first computes a hash over all items in its set, and sends this fingerprint to the other peer. That peer then computes the fingerprint over its items as well. If the fingerprints match, they are done reconciling.
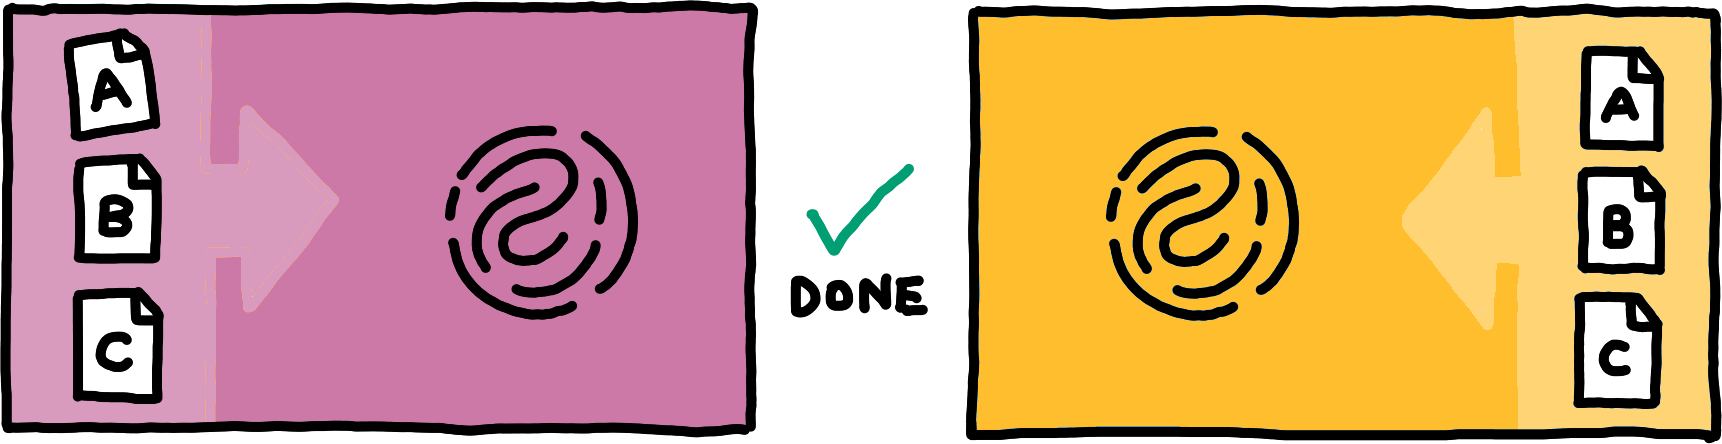
If the fingerprints do not match, there are two options. First, the peer can split its set in half and then initiate set reconciliation for each half concurrently (by transmitting its hashes for both halves). Second, if the set is sufficiently small, the peer can instead simply transmit its items in the set. The other peer responds to this with all other items that it held in the set, completing the process of reconciliation.
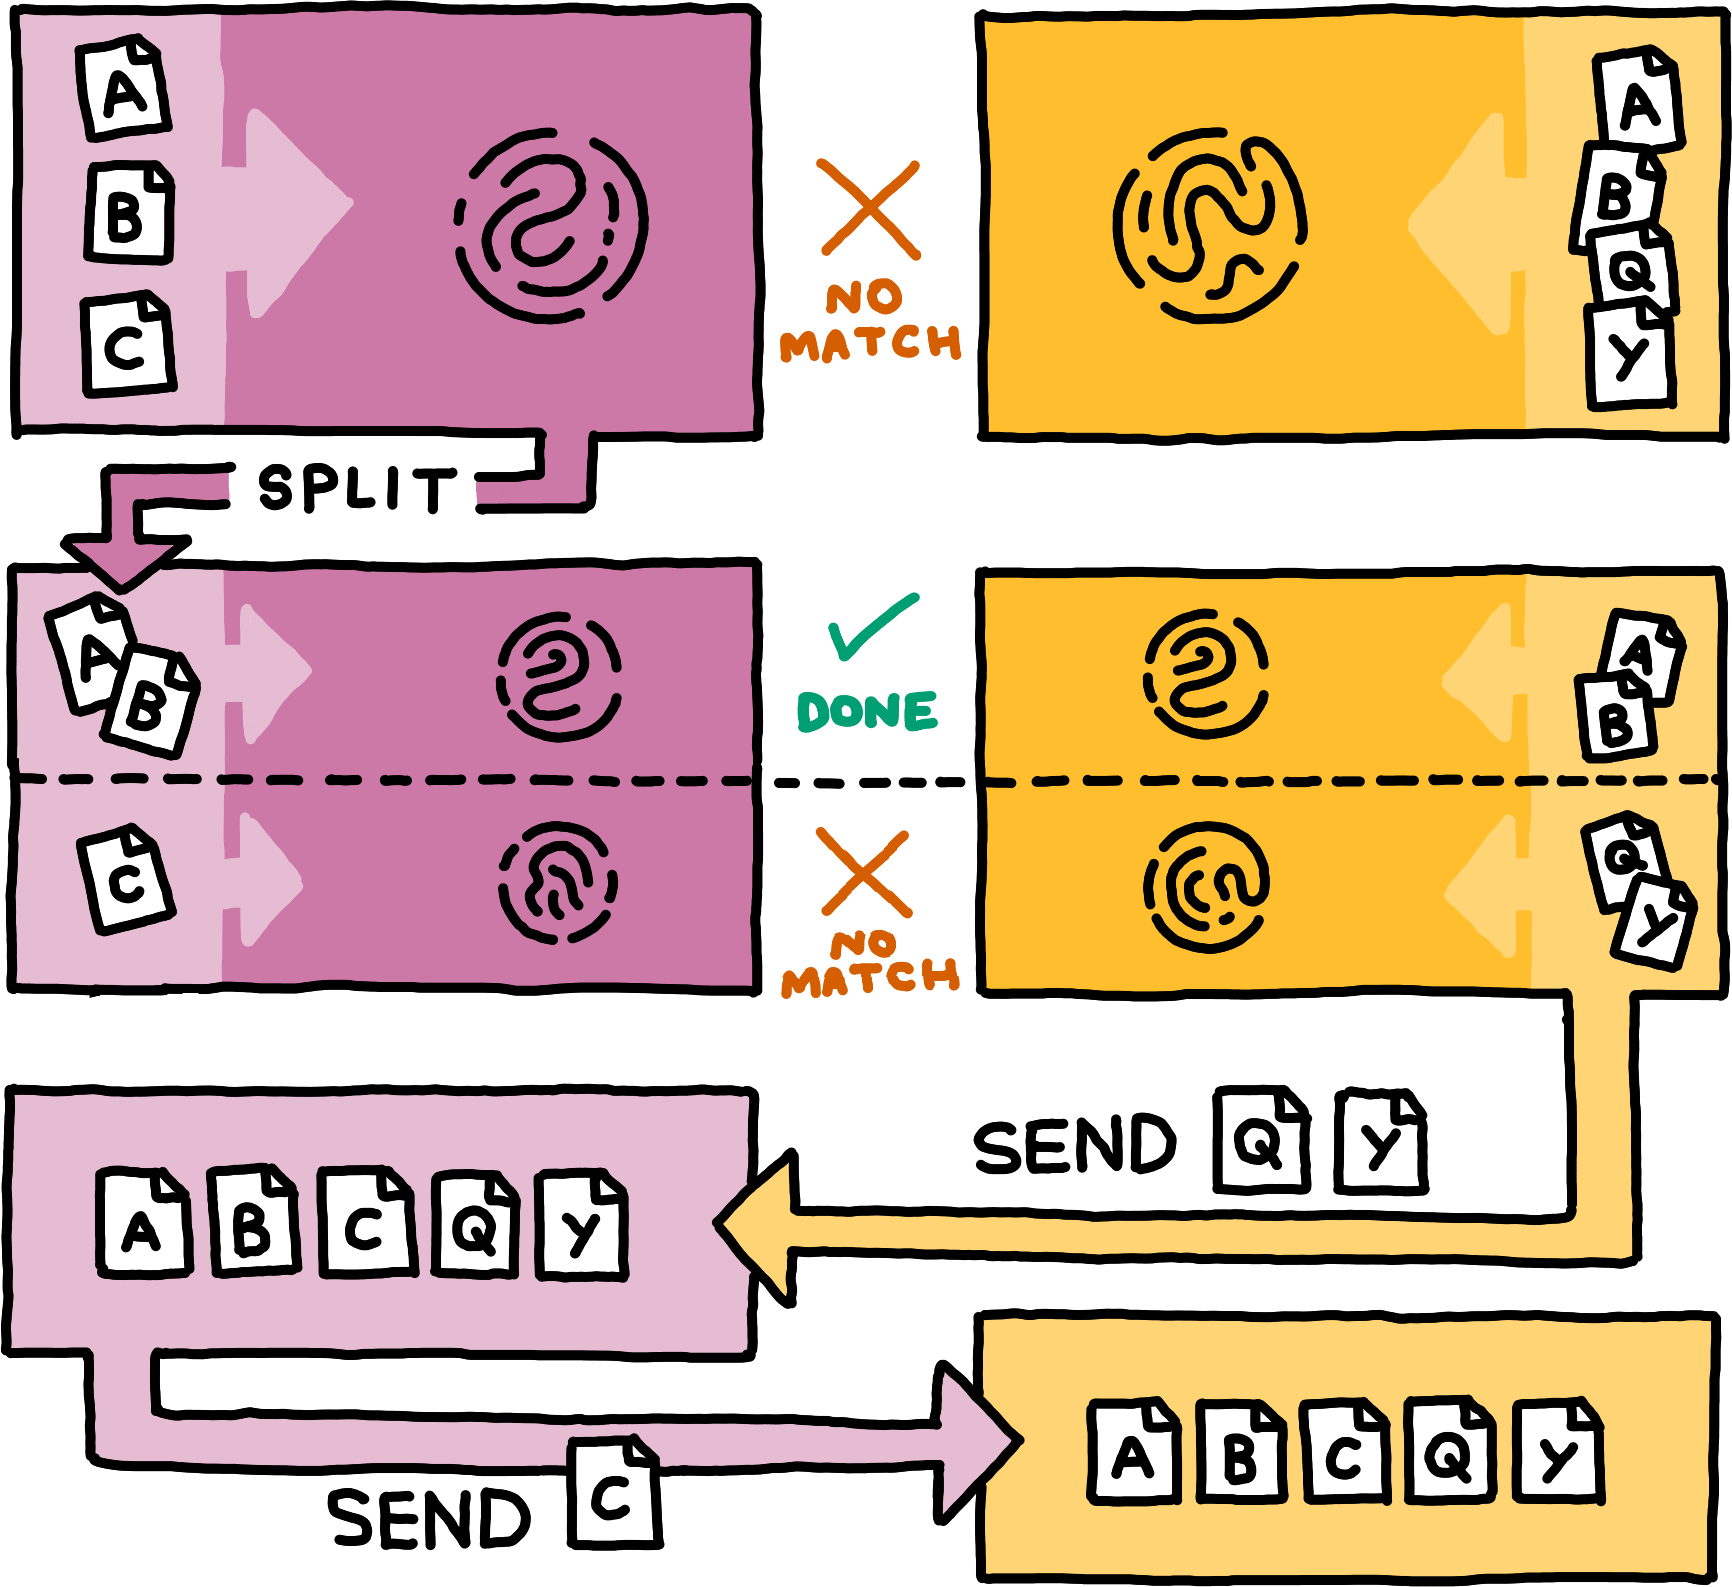
A and B, and another AreaSlice including C, and sends these AreaSlices and their fingerprints to Betty. Betty produces a matching fingerprint for the first AreaSlice. As the other, mismatched AreaSlice includes so few AuthorisedEntries, Betty sends her AuthorisedEntries Q and Y to Alfie. In response, Alfie sends AuthorisedEntry C to Betty.Overall, the peers collaboratively drill down to the differences between their two sets in a logarithmic number of communication rounds, spending only little bandwidth on those regions of the original sets where they hold the same items. Note that peers can actually split sets into arbitrarily many subsets in each step. Splitting into more subsets per step decreases the total number of communication rounds.
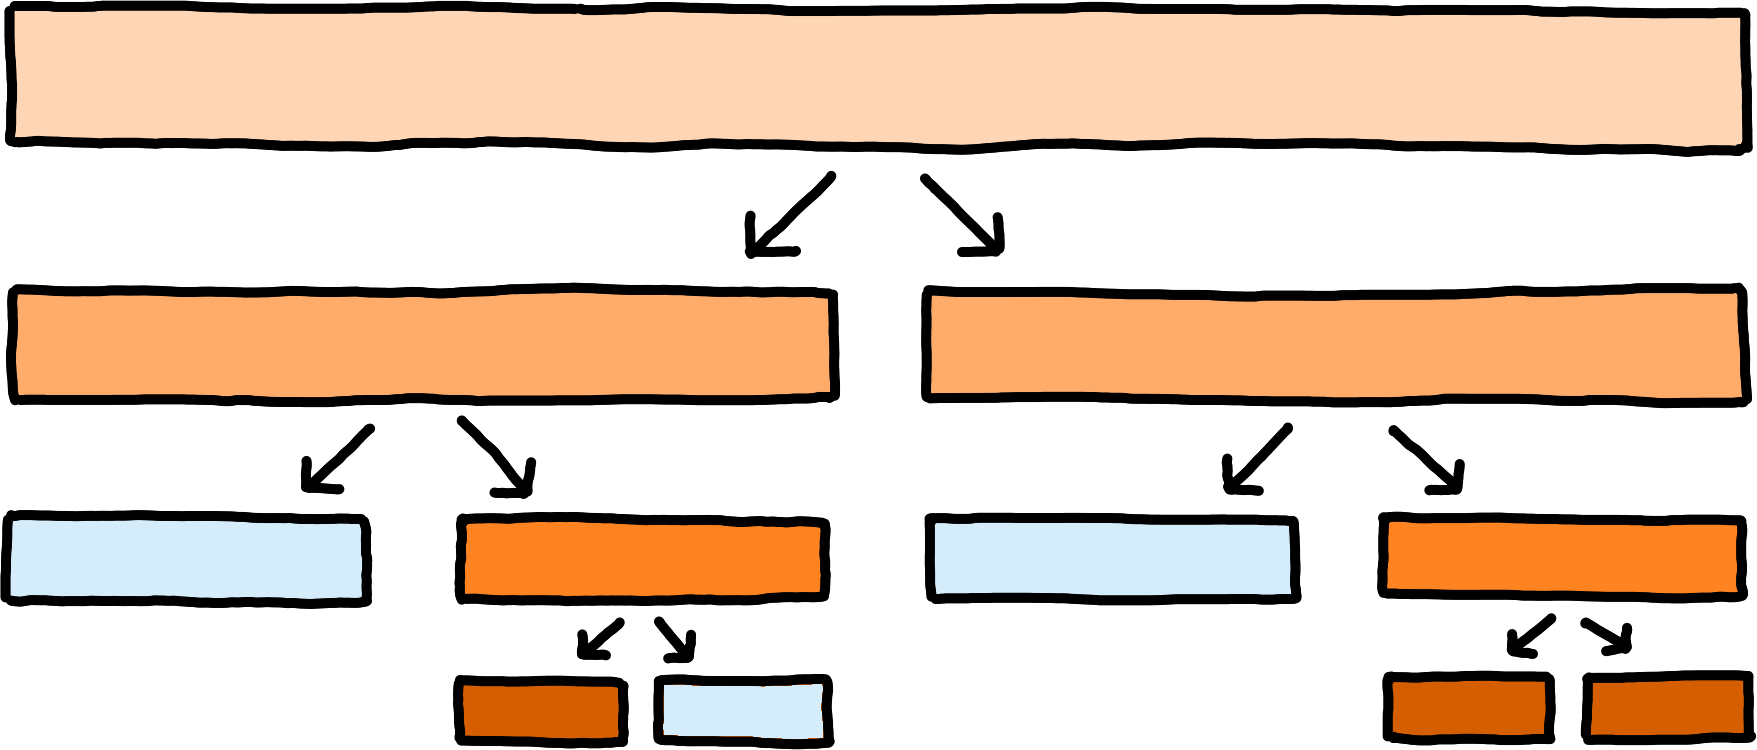
The reasons for using AreaSlices as the grouping for the reconciliation process are given in this paper by Elvio Amparore.Region-based set reconciliation takes these ideas and applies them to Willow. The core design decision is to delimit sets of LengthyAuthorisedEntries via AreaSlices. When a peer splits an AreaSlices, it is crucial for overall efficiency to not split based on volume (for example, by splitting the ReconciliationRanges in half numerically), but to split into subslices in which the peer holds roughly the same number of AuthorisedEntries.
We will call the type of hashes of LengthyAuthorisedEntries that the peers exchange Fingerprint.
Fingerprinting
Region-based set reconciliation requires the ability to hash arbitrary sets of LengthyAuthorisedEntries into values of some type Fingerprint. We now describe the technique described in the range-based set reconciliation paper for computing fingerprints efficiently. The key idea is to ensure that the Fingerprint for an AreaSlice can be assembled from precomputed Fingerprints of other, smaller AreaSlices. What we describe now is not mandatory for Willow, but it probably is a good idea.
We define the fingerprinting function in terms of some building blocks: LengthyAuthorisedEntries are mapped into a set PreFingerprint with a function that satisfies certain algebraic properties that allow for incremental computation, and PreFingerprints are then convertedThe split into PreFingerprints and Fingerprints allows for compression: the PreFingerprints might be efficient to compute but rather large, so you would not want to exchange them over the network. Converting a PreFingerprint into a Fingerprint can be as simple as hashing it with a typical, secure hash function, thus preserving collision resistance but yielding smaller final fingerprints. into the final Fingerprint.
First, we require a function fingerprint_singleton that hashes individual LengthyAuthorisedEntries into the set PreFingerprint. This hash function should take into account all aspects of the LengthyAuthorisedEntry: modifying its namespace_id, subspace_id, path, timestamp, payload_digest, payload_length, or its number of available bytes, should result in a completely different PreFingerprint.
Second, we require an associative and commutative11Classic range-based set reconciliation does not require commutativity. We require it because we do not wish to prescribe how to linearise three-dimensional data into a single order. function fingerprint_combine that maps two PreFingerprints to a single new PreFingerprint. The fingerprint_combine function must further have a neutral element fingerprint_neutral.
Third, we require a function fingerprint_finalise that maps each PreFingerprint to the corresponding Fingerprint.
Given these building blocks, we define the function fingerprint from sets of LengthyAuthorisedEntries to Fingerprint:
- applying fingerprint to the empty set yields
fingerprint_finalise(fingerprint_neutral), - applying fingerprint to a set containing exactly one LengthyAuthorisedEntry yields the same result as applying fingerprint_singleton to that LengthyAuthorisedEntry and then applying fingerprint_finalise, and
- applying fingerprint to any other set of LengthyAuthorisedEntries yields the result of applying fingerprint_singleton to all members of the set individually, then combining the resulting Fingerprints with fingerprint_combine (grouping and ordering do not matter because of associativity and commutativity), and then applying fingerprint_finalise.
| Set | Fingerprint |
|---|---|
| { } |  | {  } |  | {   } |  |
For region-based set reconciliation to work correctly, fingerprint must map distinct sets of LengthyAuthorisedEntries to distinct Fingerprints with high probability, even when facing maliciously crafted input sets. The range-based set reconciliation paper surveys suitable, cryptographically secure hash functions in section 5B (Meyer, 2023). All but the Cayley hashes use commutative fingerprint_combine functions, and are thus suitable for region-based set reconciliation. Further, fingerprint_finalise must not map distinct inpus to equal outpts; suitable choices are the identity function (if no compression is needed) or traditional, secure hash functions.